✳ the wire · analysis
CritPt v2: GPT-6 Astra leads the research-physics benchmark at 83.1%, ahead of GPT-6.1 Sol and Opus 5.5
An email the second OpenAI’s next model answers on a public API, plus every frontier launch · no card
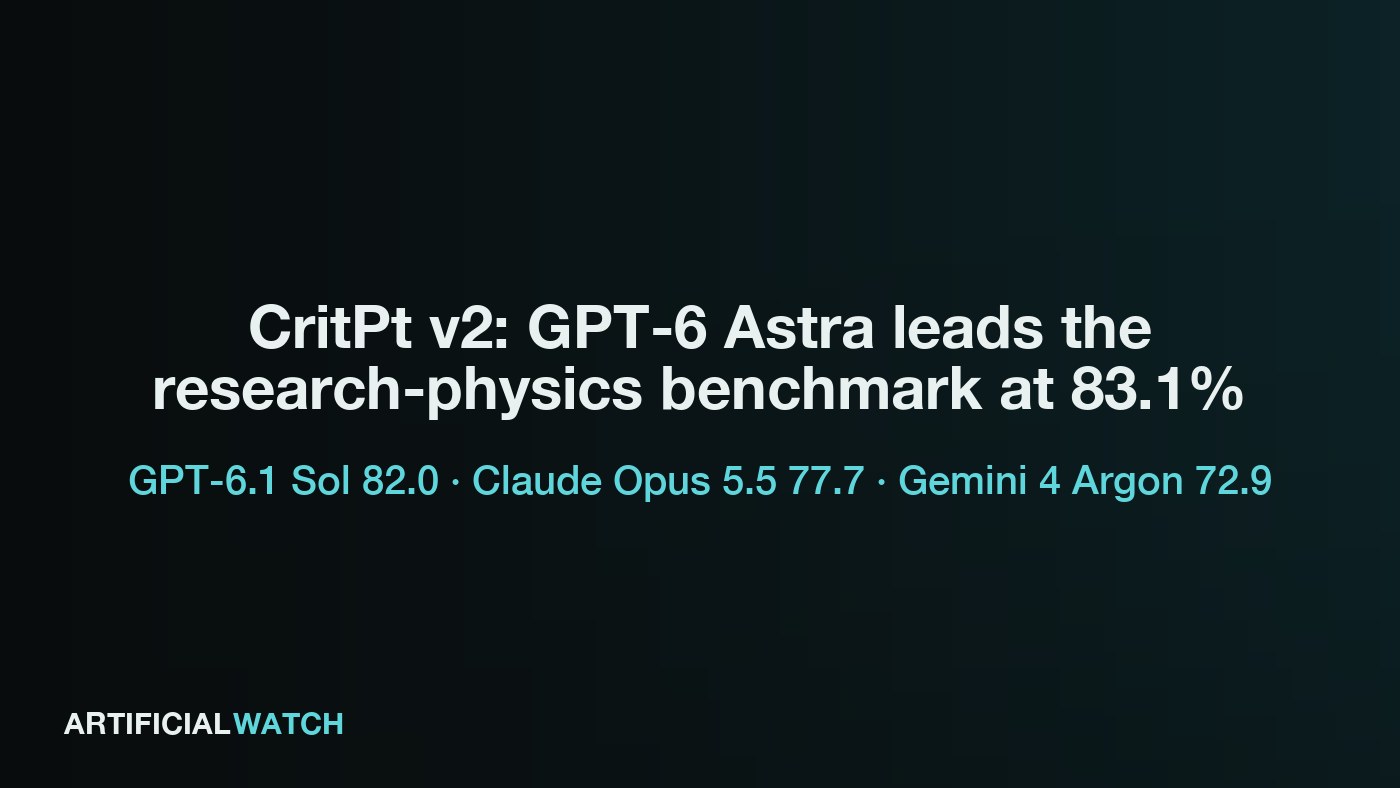
CritPt, a benchmark of unpublished, research-level physics problems, released version 2 on October 22 after four months of expert review, and GPT-6 Astra tops its new leaderboard at 83.1% average accuracy.
THE NUMBERS
From the leaderboard in CritPt's GitHub repository, read directly, averaged over 5 runs of 70 test challenges: GPT-6 Astra 83.1, GPT-6.1 Sol 82.0, Claude Opus 5.5 77.7, GPT-5.6 Sol 74.9, Muse Wonder Full 73.1, Gemini 4 Argon 72.9, Claude Fable 5.1 72.0, Muse Wonder 69.7, Grok 4.7 50.6, DeepSeek V4.1 Flash 1017 50.0 and GPT-5 28.9. The team's announcement says Astra ran at max effort with a coding tool, and that GPT-5 scored 28.9% in November 2025.
WHAT CHANGED IN V2
The team changed 47 challenges: 5 corrections to mistakes in problem statements, 19 revisions for underspecified problems, 16 grader fixes and 7 refinements, such as rewording problems to make them harder to look up. Some issues came from outside: David Louapre of Hugging Face reported 10 in June, and Anthropic sent about 65 across 31 challenges in August, of which the team accepted about 28.
WHAT WE DO NOT KNOW
How models not on the list would score, and how the v2 table will look on Artificial Analysis, which the team says will co-host the leaderboard soon. Scores from v1 are not directly comparable, since 47 challenges changed.
Source: CritPt-Benchmark/CritPt on GitHub (v2 leaderboard read directly) · the CritPt team's announcement on X · @scaling01 on X ↗ · GPT-6 Astra tracker · the bench index